

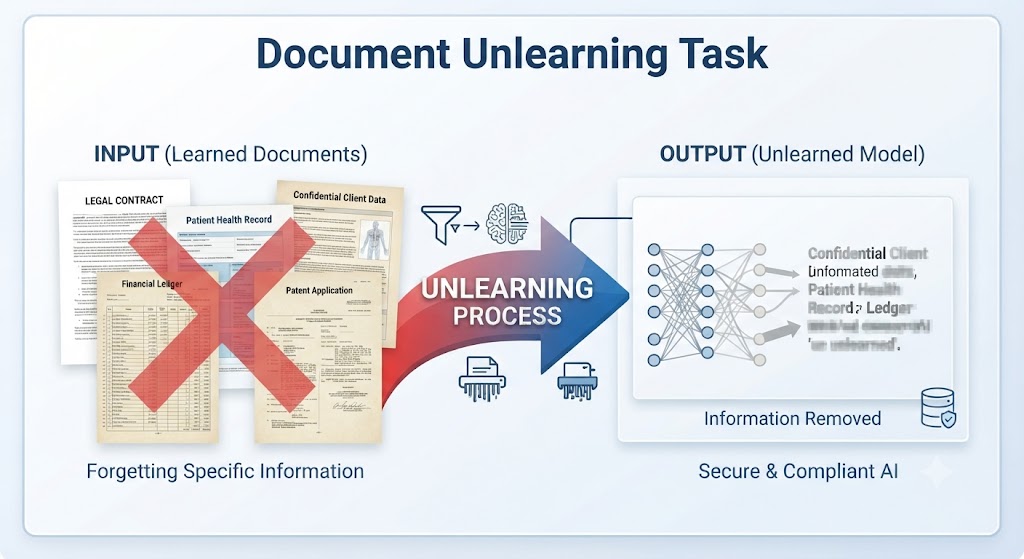
Abstract: This research advances document unlearning and secure document image understanding by addressing the critical challenge of selectively removing sensitive, proprietary, or confidential information from trained document AI models without requiring full retraining. Our work focuses on developing novel model architectures and diverse unlearning approaches tailored to complex document layouts and text structures. We explore rigorous evaluation metrics to balance unlearning efficacy with preserved model utility, tackling core challenges such as catastrophic forgetting, spatial-textual dependency, and secure compliance in multi-modal document environments.
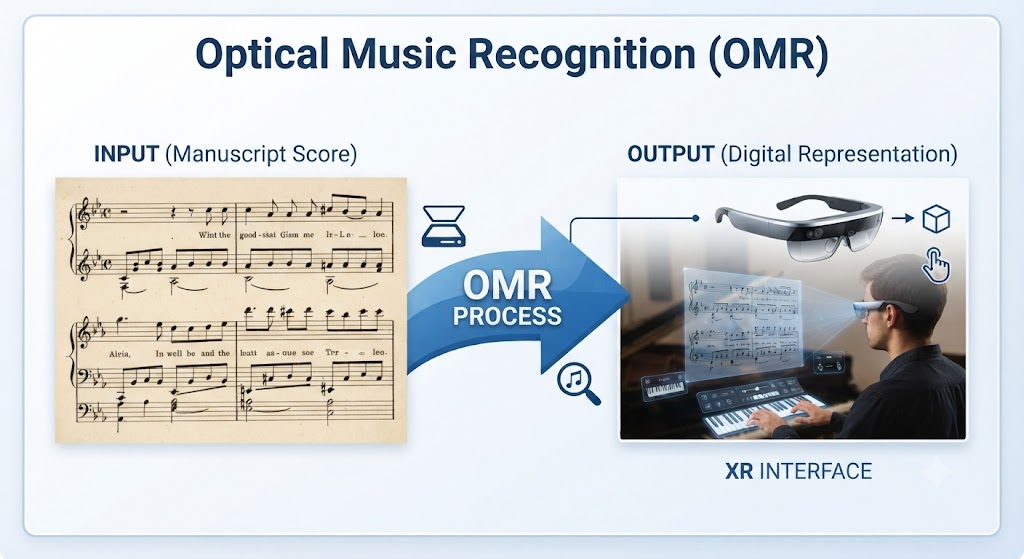
Abstract: This research advances Optical Music Recognition (OMR) by bridging the domain gap between traditional staff notation and complex heterogeneous layouts such as percussion scores. Our work encompasses comprehensive dataset creation and benchmarking (including dense object benchmarks like SWARA-Percussion), advanced deep learning models for robust symbol recognition and layout analysis, and real-time symbolic-to-immersive XR mappings that translate physical sheet music into interactive virtual reality environments.

Abstract: Architects use existing projects as reference while designing. This process aids in providing insight on how similar architectural situations were solved in the past. To search for similar projects, manual look-up through the layouts can be a cumbersome process. A fast automatic electronic technique for understanding and retrieval of similar projects need to be adopted.

Abstract: Comic-to-Video Network (C2VNet) framework converts comic strips into full-length videos with audio. The key contributions are an end-to-end synthesis framework, improved panel and text balloon segmentation, and a fully annotated dataset of an English-language comic storybook, with experimental results showcasing the framework's effectiveness.

Abstract: This project is focusing on the process of efficient digitization of physical books. Through this project the primary focus is on how to efficiently digitize a physical book from captured video stream. For this purpose, appropriate device is designed and data is collected for various downstream tasks. Also, one key contribution of this work is to identify open page image (OPI) for proper understnading of the document content.

Abstract: Our research follows an ontological approach to automatically extract the necessary indicators from an input sentence and synthesize an infographic corresponding to it. This work includes (1) the creation of a dataset, (2) an end-to-end domain-agnostic framework, and (3) demonstrating the application of the proposed framework. The results demonstrate our framework's ability to extract the necessary textual cues from real-world textual descriptions (from various domains) and synthesize meaningful infographics.

Abstract: Automatic techniques for recognizing and evaluating digital logic circuits are more efficient than traditional methods. This paper introduces LEONARDO, a hierarchical framework for synthesizing boolean expressions from hand-drawn logic gate diagrams and identifying drawing anomalies. Key contributions include the novel framework and improved anomaly detection. Extensive experiments experiments demonstrated that LEONARDO is robust to user variability, achieving a 95.2% accuracy, a 4% improvement over existing methods.